GPU dimensioneren voor industriële AI-visie-inspectie: Jetson, RTX of Xeon-6 met dubbele GPU?
Inhoudsopgave
Why "just buy a GPU" doesn't work
An industrial AI vision system has three hard limits: frame rate at the line speed, model size (params + image input resolution), and latency budget from camera capture to actuator decision. Pick a GPU too small and you drop frames; pick too big and you've over-spent and over-cooled. The right sizing comes from those three numbers and a small amount of capacity math.
Capacity math in one paragraph
For a single camera at F FPS running a model with measured L ms inference per image on a target GPU, the per-camera GPU utilisation is roughly F × L / 1000. A 30-FPS camera with a 20 ms model uses 60% of one stream; an 8-camera line at 30 FPS with the same model needs ~4.8 streams. Whatever your target GPU, validate the actual L on a sample before committing, vendor MIPS/TOPS numbers are not inference latency.
The three tiers
Tier 1, Jetson-class at the camera
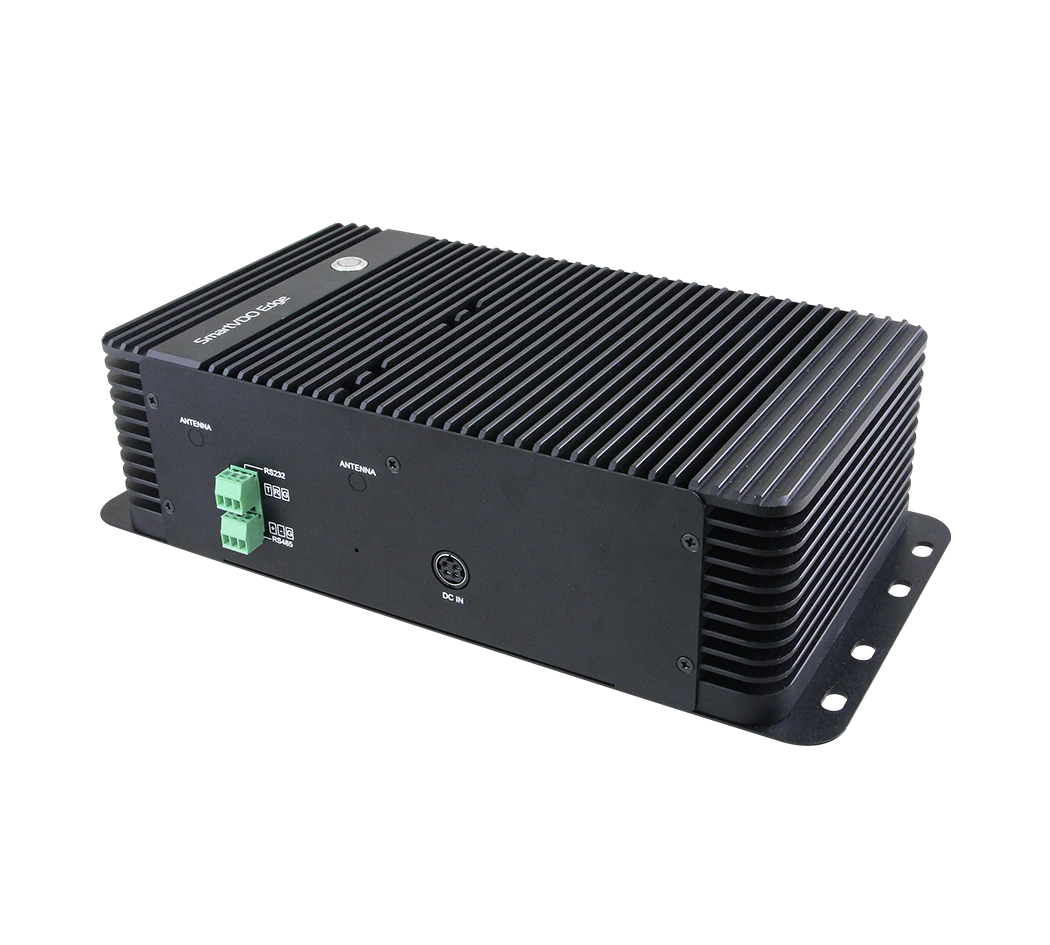
NVIDIA Jetson Orin / NX modules suit single- or low-camera-count inspection where the GPU sits at the camera or in a small inline box. Power envelope ~10 tot 60W, fanless or low-noise fan, deployable in DIN-rail or wall-mount cabinets. Best for: spot inspection, simple OCR, presence/absence, gauge reading. See Avalue's NVIDIA Solution platforms including AIB-NIAO-S, AIB-NINX-S and AIB-NW01.
Tier 2, RTX Ada in an AI Box PC
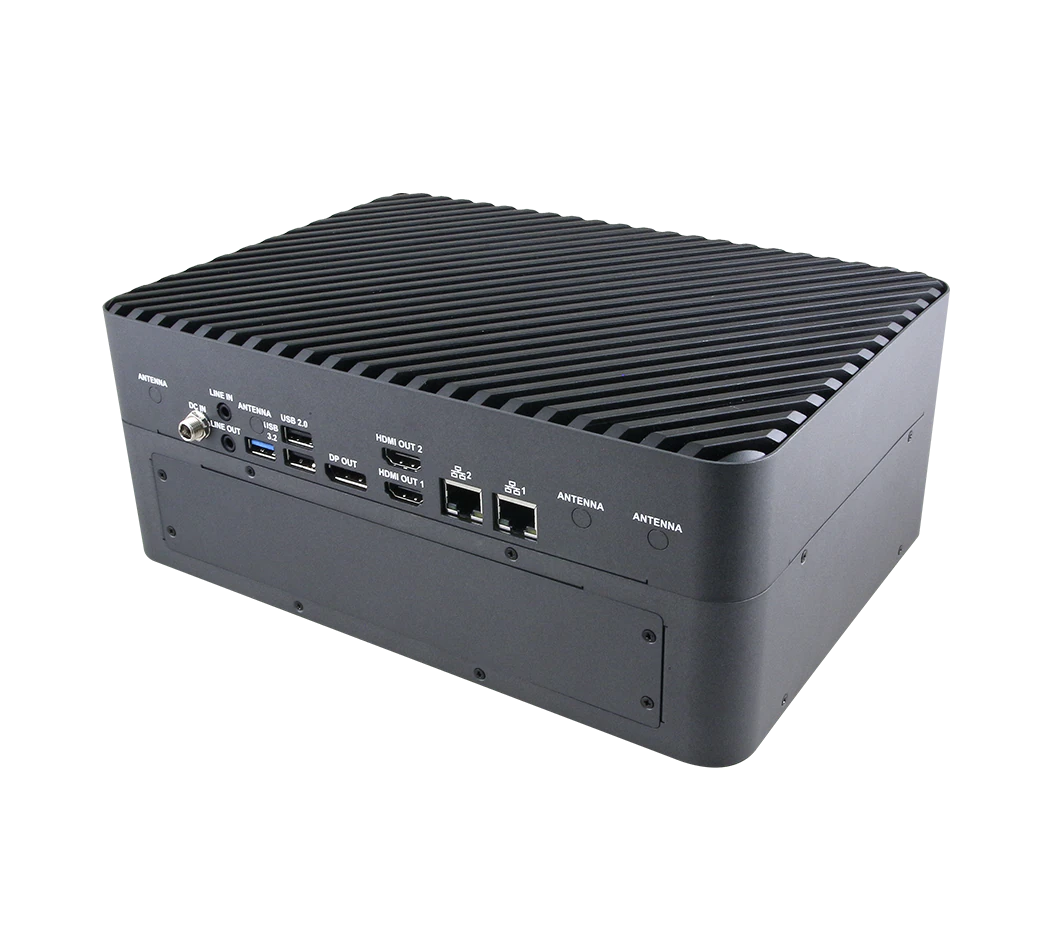
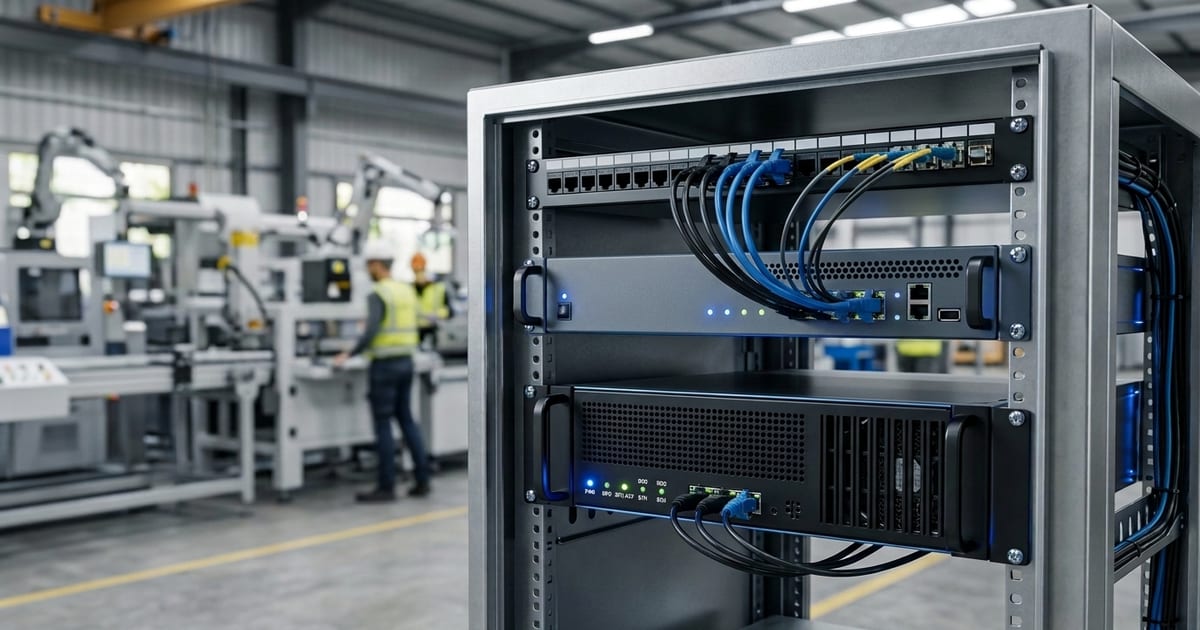
For multi-camera lines (4 tot 8 cameras), high-resolution input, or 3D model heads, an industrial box PC with a single discrete RTX Ada (e.g., RTX 2000E Ada in a sealed industrial box) is the sweet spot. Power ~70 tot 200W on the GPU, PCIe Gen4 x16, expandable for frame grabbers. The MAB-T660D ships in this tier (RTX 2000E Ada, PCIe Gen4 x16). See our MAB-T690/T660D coverage for the full architecture.
Tier 3, Xeon-6 server with dual-width GPUs
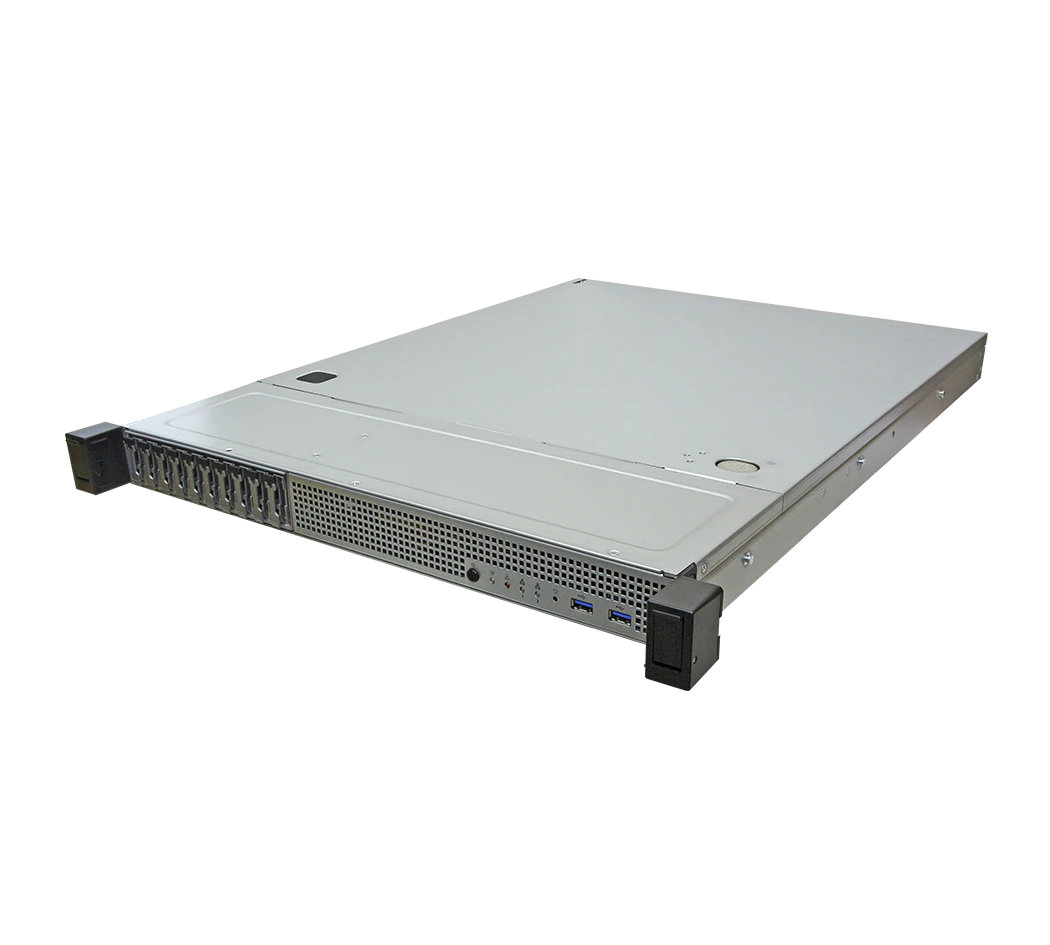
For centralised, many-camera vision, large 3D reconstruction, AOI farms or model-training/refresh, a 1U/2U server with one or two dual-width GPUs and PCIe Gen5 takes over. Avalue's Edge HPC portfolio includes the HPS-GNRU1A 1U system on a single Intel Xeon 6 processor (up to 350W TDP) with FHFL GPU expansion, and the HPS-GNRU4A server supporting four dual-width GPUs over PCIe Gen5. See our Edge HPC coverage.
How to choose
- List the cameras, their resolution and frame rate.
- Pick the candidate model (YOLO/Mask-RCNN/custom transformer) and measure inference latency on a candidate GPU with a representative image batch.
- Multiply: total stream demand = Σ (F × L / 1000) across cameras.
- Add ~30% headroom for image preprocessing, drift and future model upgrades.
- Pick the smallest tier that covers the demand and meets the latency budget, Tier 1 if total < one Jetson stream, Tier 2 for multi-camera single-box lines, Tier 3 for centralised multi-line or training workloads.
Pitfalls to avoid
- Sizing on TOPS instead of measured FPS
- Forgetting power and cooling, an RTX Ada in a sealed box may thermal-throttle in summer
- Single-GPU bottleneck when a frame grabber needs PCIe Gen5 x16 bandwidth
- No upgrade path when the model is replaced by a larger one a year later
Where TSL Automation fits
TSL Automation supplies all three tiers, Jetson-class AIB platforms, RTX-Ada-equipped box PCs and Xeon-6 GPU servers. Contact our team with your camera count, frame rate, model and latency budget and we'll shortlist the smallest tier that covers it.
Veelgestelde vragen
TSL Automation Solutions
Hoofd Marketing, TSL Automation Solutions
Sanjana schrijft over trends in industriële automatisering, productlanceringen en technologische inzichten voor TSL Automation Solutions, een in Mumbai gevestigde distributeur van HMI, panel-pc en embedded computersystemen voor fabrikanten in India en wereldwijd.
Hulp nodig bij het kiezen van het juiste product?
Ons team in Mumbai adviseert u over de juiste HMI, panel-pc of het juiste embedded systeem voor uw toepassing.
Neem contact op met TSL Automation